Runway bets on video pretraining and open weights for robotics
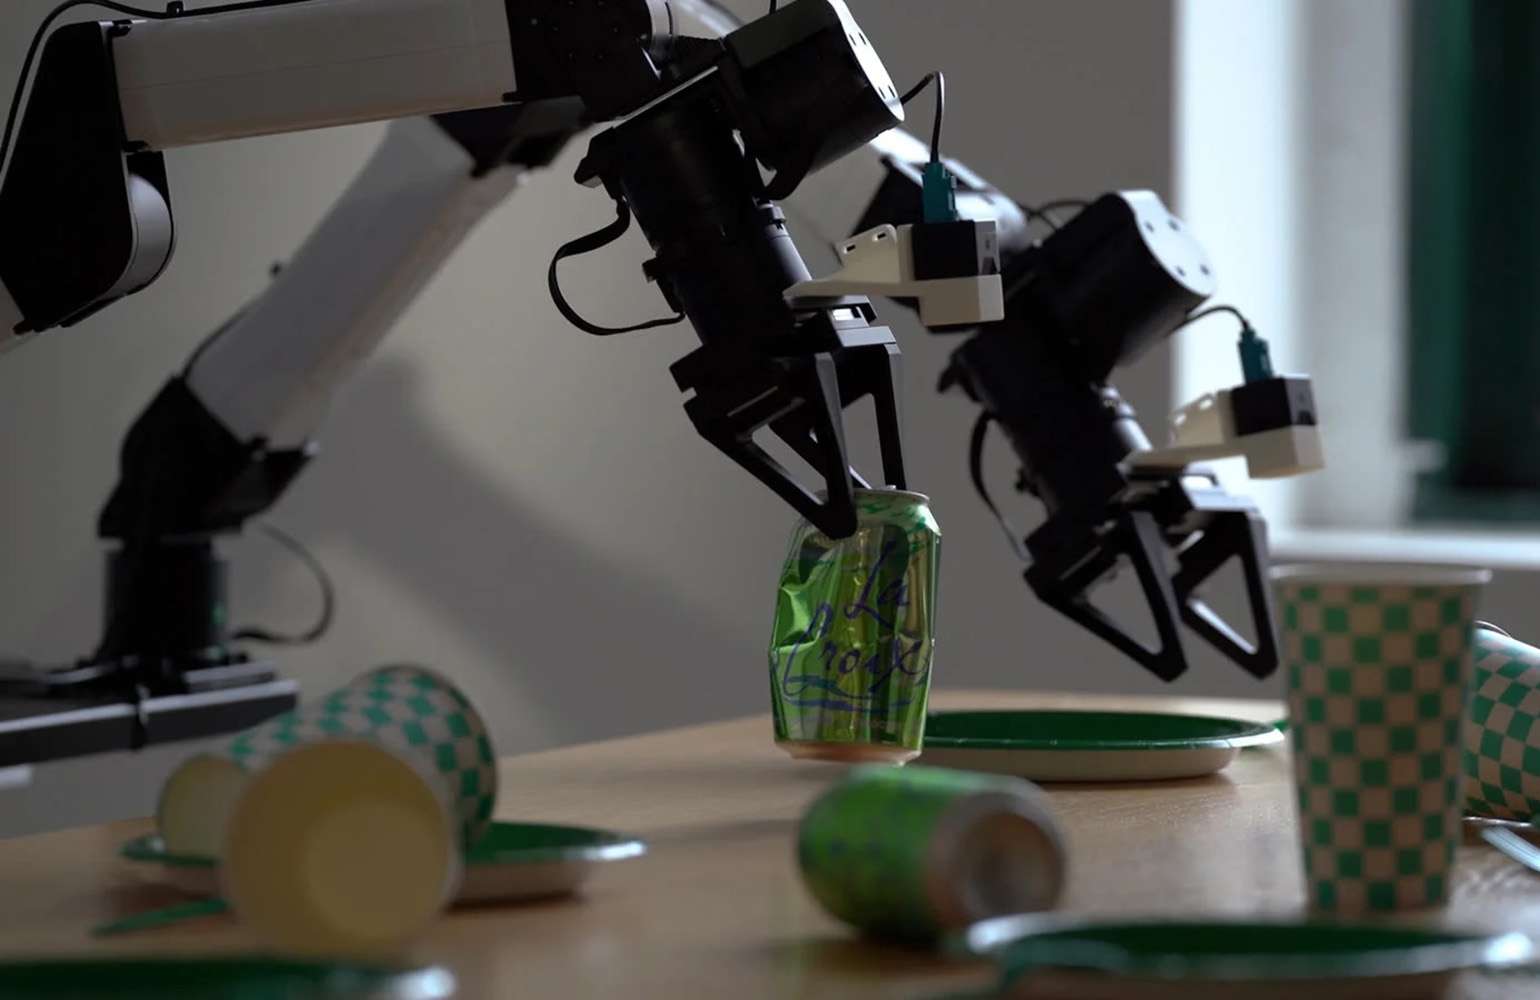
Paying operators to log thousands of hours teleoperating grippers will never produce the data volume modern foundation models demand. As reported by The Robot Report, Runway is taking a different path with Praxis-1, bootstrapping robot action models out of large-scale video pretraining instead of relying purely on demonstration fleets. It shares some obvious parallels with NVIDIA Cosmos and its world foundation models, using video to build physical intuition before touching real hardware. Is this the new direction of robotics? That remains to be seen in production, but it is an interesting approach.
Bridging passive video to physical actuation is notoriously difficult. Predicting the next video frame is fundamentally different from managing contact dynamics, torque, and spatial uncertainty on bare metal. Runway claims policy simulation inside its world model achieves a 0.95 correlation with physical trials across different embodiments. I want to see independent verification on that benchmark once early partners deploy it further, but treating physical intuition as a byproduct of web-scale video pretraining is the right engineering direction.
The most important detail here is the commitment to open weights. Physical control loops have tight latency constraints and run on constrained local compute; closed cloud APIs are a dead end for real-time actuation. Letting robotics developers inspect, adapt, and fine-tune weights directly on their own hardware is how embodied foundation models actually gain traction outside the lab.